Data Engineering
Serverless Data Lake with Quality Checks
AWS CDK PoC for bounded public-data ingestion, Spark validation, partitioned S3 Parquet and Athena quality reporting.
Problem
Demonstrate a practical, repeatable batch lake pattern that separates clean and rejected rows, exposes data-quality metrics and makes analysis queryable without claiming unverified production results.
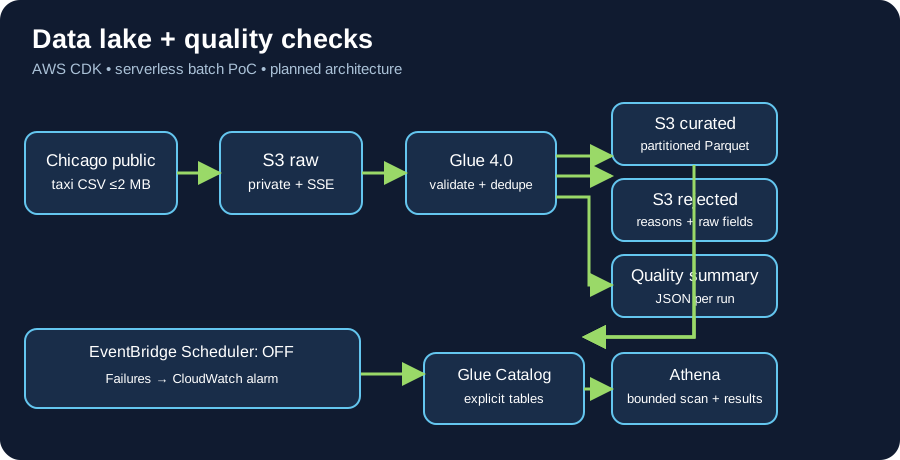
Architecture
CDK provisions four encrypted, private S3 zones (raw, curated, rejected, Athena results), explicit Glue catalog tables, a Glue 4.0 Spark ETL job with schema/null/range/deduplication checks, partitioned Parquet, JSON audit summaries, and an Athena workgroup with a per-query scan cap. An optional disabled EventBridge Scheduler trigger and a CloudWatch job-failure alarm are included. A bounded Chicago public taxi sample ingestion script, SQL examples, tests and manual OIDC deployment workflow live in the repository. The image field names the portfolio asset; the demoUrl is a proposed repository URL, not a hosted demo.
Results
Pending deployment. Local CDK assertion tests and Spark-independent validation unit tests are included, but no deployed quality figures, job duration, Athena queries, alarm behavior or observed costs are claimed. Capture these after a sandbox deployment.